

Python concurrent.futures Guide: ThreadPool vs ProcessPool
- Home
- Python concurrent.futures Guide: ThreadPool vs ProcessPool


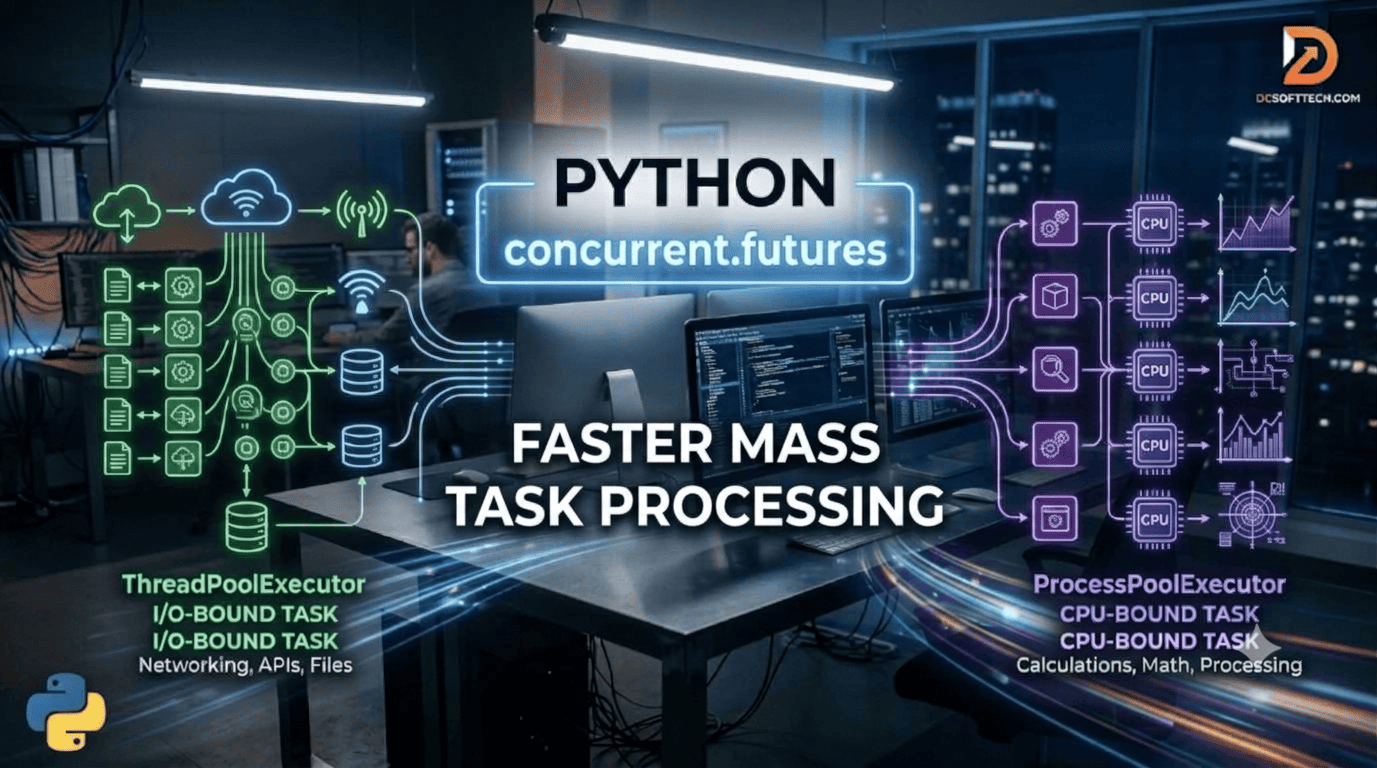
When your Python program has to handle hundreds of API requests, read and write thousands of files, or perform heavy mathematical computations, running them sequentially creates a massive bottleneck. Introduced in Python 3.2, the concurrent.futures module provides a high-level interface to optimize and streamline parallel and asynchronous processing.
In this article, DCSOFT will guide you through the detailed mechanics of concurrent.futures, how to choose between ThreadPoolExecutor and ProcessPoolExecutor, and practical examples to multiply your application’s speed.
concurrent.futures? Why Use It?concurrent.futures is a built-in Python library providing a high-level abstraction interface for executing asynchronous calls using Threads or Processes.
Compared to low-level modules like threading or multiprocessing, concurrent.futures offers several outstanding advantages:
Unified API: Uses a consistent structure for both Threading and Multiprocessing.
Automatic Pool Management: Manages worker lifecycles and reuses resources efficiently without manual handling (such as creating, starting, and joining individual threads).
Easy Result Management: Through the Future object, you can easily check status, cancel tasks, or retrieve return values once tasks complete.
To optimize performance in Python, the core step is identifying the exact nature of your workload. Python is affected by the GIL (Global Interpreter Lock), a mechanism that prevents multiple native threads from executing Python bytecodes at once.
Plaintext
                  ┌─────────────────────────────────────────┐
                  │            Identify Task Type           │
                  └────────────────────┬────────────────────┘
                                       │
                     ┌─────────────────┴─────────────────┐
                     ▼                                   ▼
          ┌─────────────────────┐             ┌─────────────────────┐
          │      I/O-Bound      │             │      CPU-Bound      │
          │ (Files, APIs, DB)   │             │  (Image, AI, Math)  │
          └──────────┬──────────┘             └──────────┬──────────┘
                     │                                   │
                     ▼                                   ▼
        ┌─────────────────────────┐         ┌─────────────────────────┐
        │   ThreadPoolExecutor    │         │   ProcessPoolExecutor   │
        │ (Bypasses GIL for I/O)  │         │ (Separate OS Processes) │
        └─────────────────────────┘         └─────────────────────────┘
Typical tasks: Web scraping, calling third-party APIs, database querying, reading/writing files from disk.
Mechanism: When a thread waits for network or disk response (I/O wait state), the GIL is released so other threads can run. This dramatically accelerates the program.
Typical tasks: Image/video processing, complex mathematical calculations, machine learning model training, data compression.
Mechanism: Spawns entirely separate Python processes (each with an independent GIL and dedicated CPU core). This maximizes all available CPU cores (Multi-core).
ThreadPoolExecutor for I/O-bound TasksSuppose you need to send requests to fetch data from a list of multiple URLs. If run sequentially, the total waiting time is the sum of all requests.
executor.map() (Preserves Result Order)executor.map() is ideal when you want results returned in the exact order of the input list.
Python
import time
from concurrent.futures import ThreadPoolExecutor
import requests

urls = [
    "https://httpbin.org/delay/2",
    "https://httpbin.org/delay/1",
    "https://httpbin.org/delay/3",
    "https://httpbin.org/delay/1"
]

def fetch_url(url):
    response = requests.get(url)
    return f"Done {url} Status: {response.status_code}"

start_time = time.time()

# Use Context Manager (with) to automatically shut down the pool when done
with ThreadPoolExecutor(max_workers=4) as executor:
    results = executor.map(fetch_url, urls)

    for result in results:
        print(result)

print(f"Total completion time: {time.time() - start_time:.2f} seconds")
Result: Total time drops to around 3 seconds (instead of 7 seconds if run sequentially).
executor.submit() and as_completed() (Receive Results Immediately)If you want to process the results of whichever task finishes first without waiting for others, use submit() combined with as_completed().
Python
from concurrent.futures import ThreadPoolExecutor, as_completed
import requests

urls = [
    "https://httpbin.org/delay/3",
    "https://httpbin.org/delay/1",
    "https://httpbin.org/delay/2"
]

def fetch_url(url):
    res = requests.get(url)
    return url, res.status_code

with ThreadPoolExecutor(max_workers=3) as executor:
    # Submit each task and store the Future object
    futures = [executor.submit(fetch_url, url) for url in urls]

    # Retrieve results as soon as any task completes
    for future in as_completed(futures):
        url, status = future.result()
        print(f"Completed: {url} -> Status {status}")
ProcessPoolExecutor for CPU-bound TasksWhen processing heavy computational algorithms across a large number of elements, ProcessPoolExecutor is mandatory.
Important Note on Windows: Code running
ProcessPoolExecutormust be wrapped inside anif __name__ == '__main__':block to prevent recursive process creation errors.
Python
import time
from concurrent.futures import ProcessPoolExecutor

# Prime number checking function (CPU-intensive task)
def is_prime(n):
    if n < 2:
        return False
    for i in range(2, int(n ** 0.5) + 1):
        if n % i == 0:
            return False
    return True

numbers = [100000007, 100000037, 100000039, 100000049, 100000081]

if __name__ == '__main__':
    start = time.time()

    with ProcessPoolExecutor() as executor:
        results = list(executor.map(is_prime, numbers))

    print(f"Results: {results}")
    print(f"Parallel processing time: {time.time() - start:.2f} seconds")
To optimize performance and prevent system resource exhaustion, apply these principles:
Determine a Reasonable max_workers Count:
For ThreadPoolExecutor: Workers can range from 5 to 30 depending on network/I/O latency.
For ProcessPoolExecutor: Python defaults to the number of available CPU cores (os.cpu_count()). Do not exceed physical cores, as it increases Context Switching overhead.
Exception Handling:
If a function raises an Exception inside a thread/process, that exception only surfaces when you call future.result(). Always wrap try...except around future.result().
Prioritize Context Managers (with blocks):
Helps automatically clean up resources and wait for workers to finish (shutdown(wait=True)) before exiting the program.
The concurrent.futures module is a powerful and accessible tool that helps Python developers drastically accelerate program execution speeds. By clearly distinguishing between I/O-bound (using ThreadPoolExecutor) and CPU-bound (using ProcessPoolExecutor) tasks, you can seamlessly and optimally build applications that handle batch operations with ease.
If you are developing complex web applications, enterprise software solutions, or big data processing systems, contact DCSOFT today for professional software architecture consulting!